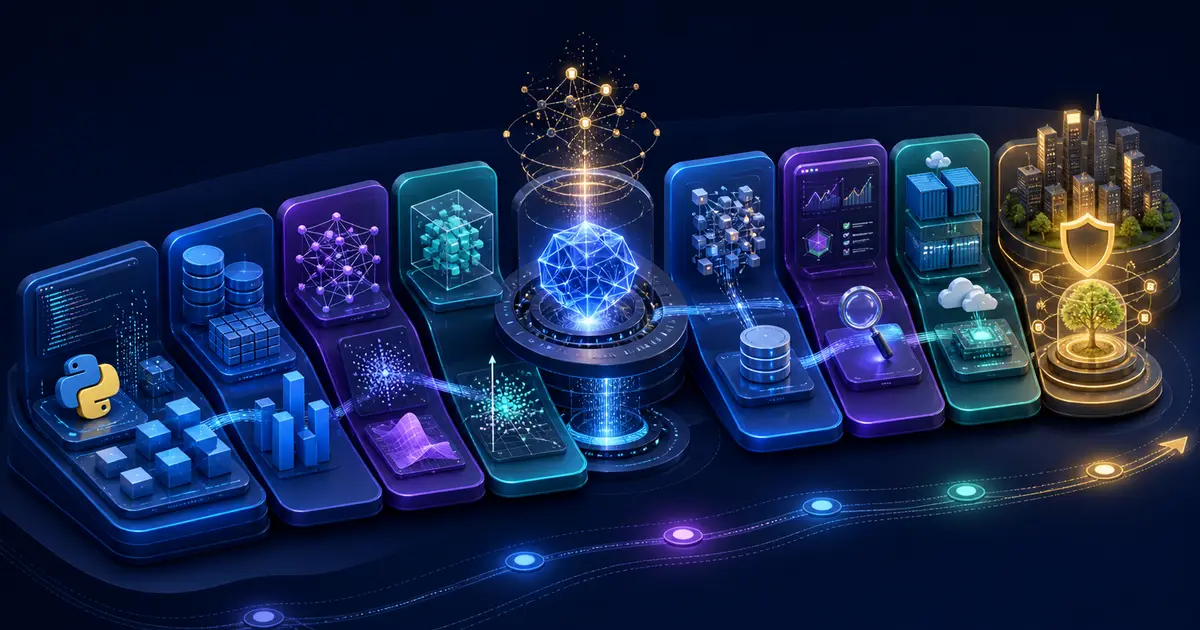
TL;DR: RAG is a data pipeline, not just a prompt. Learn ingestion, chunking, embeddings, vector search, context assembly, citations, evaluation, and failure handling in that order.
Start with a Narrow Corpus
Use a small set of stable documents such as product policies or engineering notes. Extract text, preserve metadata, split it into meaningful chunks, and make the process repeatable.
Make Retrieval Inspectable
Store document identifiers and chunk metadata with each vector. During development, show which chunks were retrieved and why. If retrieval is wrong, changing the prompt will not fix the system.
Add Answer Quality Checks
Create questions with expected sources, then measure retrieval recall, citation correctness, answer relevance, latency, and cost. Include questions whose answers are absent from the corpus.
Production Concerns
Plan for stale documents, permissions, prompt injection, empty retrieval, model timeouts, and sensitive data. A trustworthy RAG system can say that its source material does not contain an answer.