TL;DR: Deploy a Next.js application on a Hostinger VPS as a supervised Node.js service behind an HTTPS reverse proxy. Build a standalone artifact, keep secrets outside the release, expose only the intended public ports and test restart, rollback and data recovery. This guide uses Ubuntu, systemd and Nginx for a small single-server deployment.
Choose VPS for a concrete requirement
A VPS is useful when your Next.js product needs operating-system control, custom services or a deployment layout you maintain yourself. It also makes your team responsible for patching, access, supervision, monitoring and recovery. Do not buy a server before confirming that someone will own those tasks.
There is also a managed route. Hostinger documents Node.js hosting options on eligible plans. Evaluate that workflow when the application fits and you prefer less system administration. The VPS path below is intended for teams choosing control deliberately.
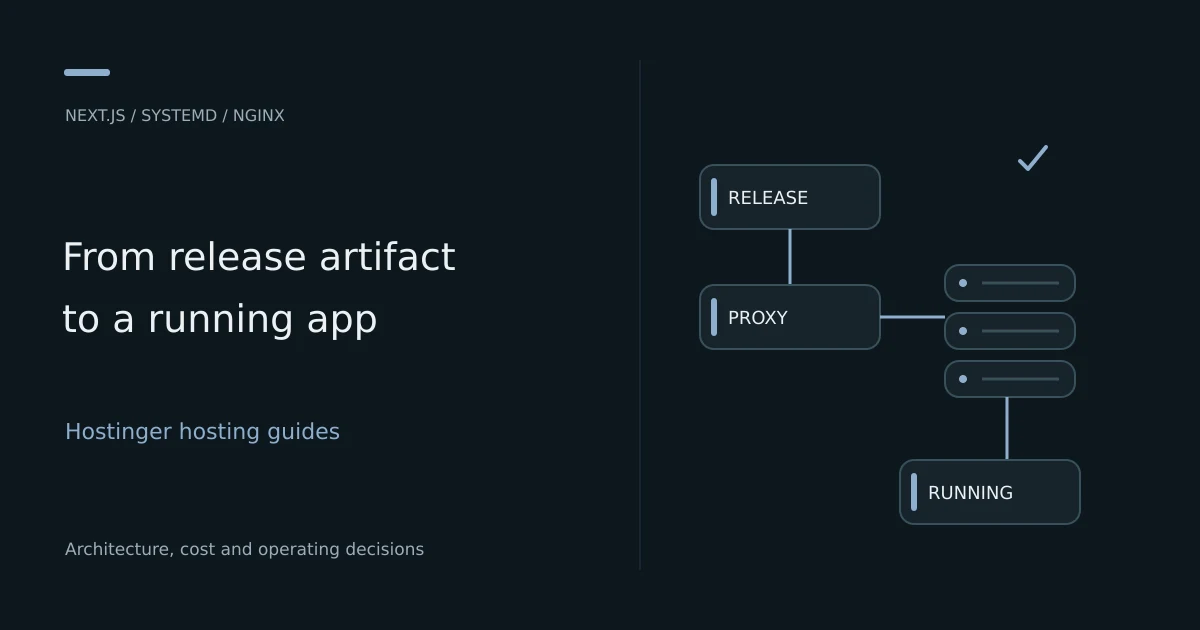
The deployment model is simple: DNS points to the server, Nginx receives public HTTP and HTTPS traffic, and a Node process listens on loopback. The database can be external or private on the same machine. Customer uploads and durable state must live outside replaceable release artifacts.
Can you host Next.js on Hostinger?
Yes, using a compatible managed Node.js workflow or a VPS you administer. Choose based on server rendering, API routes, persistence, background services and runtime requirements. A static export is a separate option with a different feature set; do not assume every application can be converted to static files without changing behavior.
Next.js frontend with a PHP backend on Hostinger VPS
Run the two runtimes as separate services behind deliberately configured proxy routes or hostnames. Nginx can forward the Next.js hostname to Node and route the PHP application through its supported PHP-FPM setup. Give each service its own secrets, permissions and deployment procedure, and test authentication across the boundary.
Decide whether the browser calls the backend on the same origin or a separate API hostname. Cross-origin requests need the correct CORS and cookie settings; a same-origin proxy still needs route ownership so Next.js and PHP do not both claim the same path. Keep database access private and align backup recovery for both applications.
This walkthrough installs the Next.js service. Configure PHP from the PHP-FPM documentation for the selected version and test its proxy configuration separately. Treating two runtimes as one unexplained process makes failures and upgrades harder to diagnose.
Confirm prerequisites and assumptions
Use an Ubuntu server you administer, a domain whose DNS you control, SSH key access and a repository with a committed lockfile. The application should already build locally and have a working production start behavior. Schedule a maintenance window if this replaces an existing production system.
Install a supported Node.js LTS release compatible with the project's Next.js version using your organization's approved installation method. The Node.js release schedule identifies supported lines. Use the same major runtime in build and production. Commands below assume the production executable is /usr/bin/node; verify and adjust it if your installation differs.
This is a single-instance example, not a multi-server high-availability design. It assumes no CDN-specific caching requirements and no separate WebSocket server. If you use several instances, review shared cache behavior, encryption keys, version consistency and deployment coordination in the Next.js self-hosting guidance.
Prepare the server and access boundary
Apply operating-system updates and install the proxy and certificate tooling. Keep a provider console available while changing SSH or firewall rules. Verify your authorized SSH access remains possible before closing the original session.
# Ubuntu host, run by an administrator with sudo access
sudo apt-get update
sudo apt-get upgrade
sudo apt-get install -y nginx certbot python3-certbot-nginx
command -v node
node --version
npm --version
sudo ss -lntup
Use named administration accounts and SSH keys. Configure both the provider firewall and the host firewall according to your access policy. Permit the chosen SSH route, HTTP and HTTPS; keep the application port and database ports private. Verify the result from another machine rather than assuming a firewall screen proves actual reachability.
Do not run the application as root. Root is appropriate for system setup, not for parsing customer requests. Keep the deployment account, service account and business billing access separate where practical so one compromised credential does not control the entire system.
Add a small health endpoint
A health endpoint provides a stable way to check whether the application process can serve a request. Keep it inexpensive and avoid returning secrets, internal addresses or database credentials. Separate basic process health from deeper dependency checks when their failure semantics differ.
// app/api/health/route.ts
export const dynamic = 'force-dynamic';

export async function GET() {
  return Response.json({ status: 'ok' }, { headers: { 'Cache-Control': 'no-store' } });
}
This endpoint does not prove the database or payment gateway works. Add a protected or separately monitored readiness check when necessary, with bounded timeouts. Business acceptance should still exercise login, a representative read and a representative write.
Avoid making the public liveness endpoint depend on every third-party service. A temporary email-provider failure should not necessarily make the process look dead and trigger repeated restarts. Choose health semantics that help operators distinguish application failure from dependency degradation.
Build a standalone release artifact
Enable standalone output in the existing Next.js configuration. Preserve any plugins or other required options already present in the project. Do not replace a production configuration with this minimal example wholesale.
// next.config.ts: merge this option into your existing config
import type { NextConfig } from 'next';

const nextConfig: NextConfig = {
  output: 'standalone',
};

export default nextConfig;
Build as an unprivileged user from a reviewed revision. npm ci expects a committed package lock and installs its resolved dependency graph. Run the project's meaningful checks before creating the artifact. If the build requires external services or secrets, provide them through a controlled build environment rather than committing them.
# In your reviewed application checkout, not as root
npm ci
npm run build
mkdir -p public
cp -a public .next/standalone/
mkdir -p .next/standalone/.next
cp -a .next/static .next/standalone/.next/
Standalone output contains the files needed by its server entry point, but public assets and static output require the accompanying copy step in this deployment layout. Verify the artifact before transfer. For a monorepo, output paths can differ; inspect the actual generated tree and adjust the entry point.
Build-time public environment values become part of browser assets. Changing a runtime environment file will not rewrite them. Plan environment-specific builds where required and never put a secret into a variable intentionally exposed to browser code.
Check artifact compatibility before transfer
Build native dependencies for the production operating system and CPU architecture. A standalone artifact created on a developer's laptop may contain platform-specific binaries that cannot run on the Linux VPS. Use a compatible Linux build environment or the project's approved container build rather than assuming the JavaScript entry point makes every dependency portable.
Record the Node.js major version, application revision and build environment alongside the artifact. If the application performs image processing or uses a native database client, include those paths in acceptance testing. A health endpoint can succeed while the first real request requiring a native module fails.
Keep build output separate from production data. Inspect the archive before transfer and exclude local environment files, development exports and unrelated workspace files. A reproducible artifact should contain exactly the runtime application and required assets, with secrets supplied through the separate deployment configuration.
Create a service account and release directories
Use immutable release directories identified by revision or timestamp and a current symlink. This makes it possible to retain a previous artifact and switch releases without rebuilding on the production server. Store persistent uploads elsewhere and include them in your backup design.
# Run once on a fresh host; skip user creation if it already exists
sudo useradd --system --home-dir /srv/scapp --shell /usr/sbin/nologin scapp
sudo install -d -o root -g scapp -m 0750 /srv/scapp /srv/scapp/releases
sudo install -d -o root -g scapp -m 0750 /etc/scapp
sudo install -o root -g scapp -m 0640 /dev/null /etc/scapp/app.env
sudoedit /etc/scapp/app.env
Add server-side configuration to the environment file using NAME=value lines. Keep it out of Git, release archives and public support messages. The service below sets NODE_ENV, port and hostname explicitly; avoid conflicting entries in the file.
For the first release, copy the artifact built earlier into a new directory. The example uses a literal release name for clarity; choose a unique name for each deployment and never overwrite an existing release in place.
# Run from the checkout containing the built standalone artifact
sudo install -d -o root -g scapp -m 0750 /srv/scapp/releases/first-release
sudo cp -a .next/standalone/. /srv/scapp/releases/first-release/
sudo chown -R root:scapp /srv/scapp/releases/first-release
sudo chmod -R u=rwX,g=rX,o= /srv/scapp/releases/first-release
sudo install -d -o scapp -g scapp -m 0750 \
  /srv/scapp/releases/first-release/.next/cache
sudo ln -s /srv/scapp/releases/first-release /srv/scapp/current
Application code remains owned by root while the runtime cache directory is writable by the service account. If your application needs other writable paths, create them deliberately rather than granting write access to the entire release. This example assumes a standalone artifact whose server entry point is at the artifact root.
Supervise the process with systemd
Create /etc/systemd/system/scapp.service with the following configuration. Verify the Node executable path first. A runtime installed only under an interactive user's shell configuration may not be available to systemd.
[Unit]
Description=SoftwareCrafting Next.js application
After=network.target

[Service]
Type=simple
User=scapp
Group=scapp
WorkingDirectory=/srv/scapp/current
Environment=NODE_ENV=production
Environment=HOSTNAME=127.0.0.1
Environment=PORT=3000
EnvironmentFile=/etc/scapp/app.env
ExecStart=/usr/bin/node /srv/scapp/current/server.js
Restart=on-failure
RestartSec=5
TimeoutStopSec=30
KillSignal=SIGTERM
NoNewPrivileges=true
PrivateTmp=true
UMask=0027

[Install]
WantedBy=multi-user.target
Enable the unit and test the private application listener before configuring the public proxy. Use the service logs when startup fails; common causes include a wrong runtime path, missing secrets, a missing copied asset directory or a permission error.
sudo systemctl daemon-reload
sudo systemctl enable --now scapp
sudo systemctl status scapp --no-pager
curl --fail --silent --show-error http://127.0.0.1:3000/api/health
sudo journalctl -u scapp -n 80 --no-pager
Automatic restart helps recover from a process crash but does not fix a recurring defect. Add alerts for repeated restarts and investigate their cause. Keep journal retention bounded and avoid logging customer payloads or credentials while diagnosing a failure.
Put Nginx in front of the private listener
Create a site configuration such as /etc/nginx/sites-available/scapp. Replace app.example.com with your real hostname. The initial HTTP configuration lets you verify routing before requesting a certificate.
server {
    listen 80;
    server_name app.example.com;
    client_max_body_size 10m;

    location / {
        proxy_pass http://127.0.0.1:3000;
        proxy_http_version 1.1;
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;
        proxy_buffering off;
        proxy_read_timeout 60s;
    }
}
The example disables response buffering for streamed responses and sets an explicit upload limit. Adjust those choices to your application's needs. Do not add proxy caching to personalized routes without a correct cache design. If you use a separate WebSocket service, add and test the appropriate upgrade configuration for that route.
# On a fresh Nginx setup, create this link once
sudo ln -s /etc/nginx/sites-available/scapp /etc/nginx/sites-enabled/scapp
sudo nginx -t
sudo systemctl reload nginx
Inspect existing sites to avoid duplicate server_name entries. A successful configuration test checks syntax, not whether DNS points to the right server or whether the application works. Continue with public-path verification.
Configure DNS and HTTPS
Point the intended A record at the VPS address. Add an AAAA record only when the IPv6 route is configured and verified. An incorrect IPv6 record can create intermittent failures for users whose networks prefer it even when IPv4 tests pass.
Once DNS resolves correctly and port 80 is reachable, request a certificate. Certbot's Nginx workflow can update the server configuration; review its resulting HTTPS and redirect behavior afterward.
# Replace the hostname before running
sudo certbot --nginx -d app.example.com
sudo certbot renew --dry-run
curl --fail --silent --show-error https://app.example.com/api/health
Test the certificate hostname, redirect from HTTP, canonical domain and actual application routes. Preserve existing mail and verification records when editing DNS. If a CDN sits in front, review its TLS mode and origin settings so the browser-to-CDN and CDN-to-origin paths are both intentional.
Handle database changes and persistent data
Keep database credentials server-side and bind a local database privately. Give the application a restricted database user rather than an administrative account. Store uploads in a persistent location or object-storage service, with access control appropriate to the content.
Run schema migrations as a controlled release step. Prefer backward-compatible additions so the previous application artifact can still operate during a rollback window. A release symlink cannot undo a destructive migration or recover data overwritten by a faulty background job.
Back up the database and uploads in a recoverable combination. Define acceptable data loss and recovery time, then test restoration outside production. Hostinger's VPS recovery documentation covers provider tools; use application-aware backups as well when consistency requires them.
Release updates with an explicit rollback
For a later release, build a new artifact, copy it into a unique directory and prepare its permissions and writable cache as above. Test it on a separate port or staging environment before switching production. Retain the previous release name in the deployment record.
To switch the symlink atomically on the same filesystem, create a temporary link and rename it into place. Use a unique temporary name if your automation could run concurrently. Serialize deployments so two operators cannot switch the target over each other.
# Example only: new-release must already be copied and verified
sudo ln -s /srv/scapp/releases/new-release /srv/scapp/current.next
sudo mv -Tf /srv/scapp/current.next /srv/scapp/current
sudo systemctl restart scapp
curl --fail --silent --show-error https://app.example.com/api/health
A single-process restart can cause a brief interruption. If the business requires uninterrupted releases, design and test multiple instances, traffic switching and compatible state handling. Do not describe this simple restart procedure as zero downtime.
Test the operating behavior, not just the page
Verify the app after a controlled service restart and, during an approved window, after a server reboot. Confirm the service starts automatically and the proxy reconnects. Exercise login, data reads and writes, file handling, notifications and any scheduled work.
| Failure | Diagnostic boundary | First useful check |
|---|---|---|
| Nginx returns 502 | Proxy to application | Service status and loopback health request |
| Build succeeds but assets fail | Artifact completeness | Public and static directories in the release |
| Browser uses wrong public API URL | Build-time configuration | Values used when producing the artifact |
| Service works manually only | systemd environment or permissions | Unit file, runtime path and journal |
| Public HTTPS fails but local app works | DNS, certificate, firewall or proxy | Public resolution and Nginx configuration |
| Rollback code fails against data | Schema compatibility | Migration history and compatibility plan |
Record release identity in your operational logs and error reporting. Monitor external availability, application errors, disk growth and backup completion. An alert should point to a runbook and a named owner, not merely to a chart.
Automate the same reviewed procedure in CI
Once the manual sequence works, automate the sequence you have verified. A useful pipeline checks out a specific revision, installs locked dependencies, runs meaningful checks, builds the artifact and records its identity. Deployment should consume that artifact instead of rebuilding a different revision after approval.
Use a deployment credential with access limited to the intended service and host. Avoid giving a general CI token unrestricted root access. If a privileged release step is necessary, define a narrow administrator-owned wrapper and review its accepted inputs. A command assembled from untrusted branch names or arbitrary artifact paths can turn deployment automation into unintended shell access.
Serialize production deployments and preserve their logs. Two pipelines switching the same symlink can produce an unexpected running version even if each job reports success. Record who or what initiated the release, which revision it contained, the prior release and the smoke-test result. This makes rollback a known action rather than an attempt to guess yesterday's filesystem state.
Separate build secrets from runtime secrets. The build system may need access to private dependencies or content, while production needs database and service credentials. Grant only the access each stage requires and avoid putting either category into downloadable artifacts. Inspect the generated bundle when introducing a new public environment variable.
Define application smoke tests with business evidence
Use a dedicated production test account with deliberately limited permissions. A smoke test should verify a representative authenticated read and a safe write that can be cleaned up without affecting a real customer. If the system handles payment, use an approved testing procedure rather than making uncontrolled live transactions.
Check the external path through the actual hostname and proxy. A loopback health request can pass while DNS, certificate renewal or a CDN configuration is broken. Conversely, a cached public page can pass while the application process is unavailable. Combining external checks with private process checks gives a clearer failure boundary.
Verify background work separately. Create a controlled job, observe completion and confirm that a retry does not duplicate its business effect. Watch the application through a full scheduled-task cycle after a major release. A worker that stopped at deployment may not become visible until customers notice missing receipts or delayed imports.
Define what causes a rollback and who decides. A new error spike, failed login or broken write path may justify immediate reversal, while a cosmetic defect may permit a normal follow-up release. Include data compatibility in that decision. If the new version has already transformed records irreversibly, switching code alone may make the incident worse.
Maintain the operating system without surprising the app
Record the runtime installation method and how security updates reach the host. Package updates, Node.js changes and database maintenance belong in the operational calendar. Test major runtime changes against the application and build process before replacing the production executable.
Plan reboots and service restarts when system updates require them. Notify the responsible team, verify the latest backup and use the same post-change checks as an application release. A machine that has never rebooted since setup may hide a missing enabled service, an unavailable mount or an environment assumption inherited from a shell session.
Keep a second authorized recovery path and document its use. The provider console can help when network access is misconfigured, but access to it still depends on account ownership and recovery credentials. Confirm those arrangements before relying on them during an incident.
Review disk retention as part of maintenance. Old releases, caches and logs can accumulate even when the application's own data growth is modest. Keep a defined number of known-good artifacts and remove older ones only after verifying they are outside the rollback and investigation window. Persistent uploads and backup archives should have separate policies.
Production readiness and next steps
| Area | Acceptance evidence |
|---|---|
| Access | Named administrators, keys and recovery route verified |
| Runtime | Supported version and reproducible artifact recorded |
| Exposure | Only intended ports reachable externally |
| Release | Health check, business smoke tests and rollback rehearsed |
| Data | Restore of database and uploads completed separately |
| Operations | Alerts, retention and maintenance ownership documented |
Use this walkthrough as a small deployment baseline and adapt it to the actual application. SoftwareCrafting's DevOps and deployment service can help automate the release, harden the operating setup and document handover. Discuss your Next.js deployment with your runtime, data and availability requirements.
Frequently Asked Questions
Do I need PM2 as well as systemd?
No. This guide uses systemd to supervise the Node process. Avoid adding a second supervisor without a clear reason, because overlapping restart behavior makes failures harder to understand.
Can I run several applications on one VPS?
Yes, if resources and isolation are appropriate. Use separate service accounts, ports, secrets and proxy routes. Measure combined peaks and keep each application's persistent data and recovery process explicit.
Is this deployment zero downtime?
No. Restarting a single application process can interrupt traffic briefly. Continuous availability during releases requires a tested traffic-switching design and compatible application state.
Why did changing an environment file not change the browser's API URL?
Public build-time variables can be embedded into browser assets. Rebuild with the intended values and deploy the new artifact. Keep secrets in server-side configuration rather than public variables.